Synthesizing Market Data with Autoregressive Flow Matching
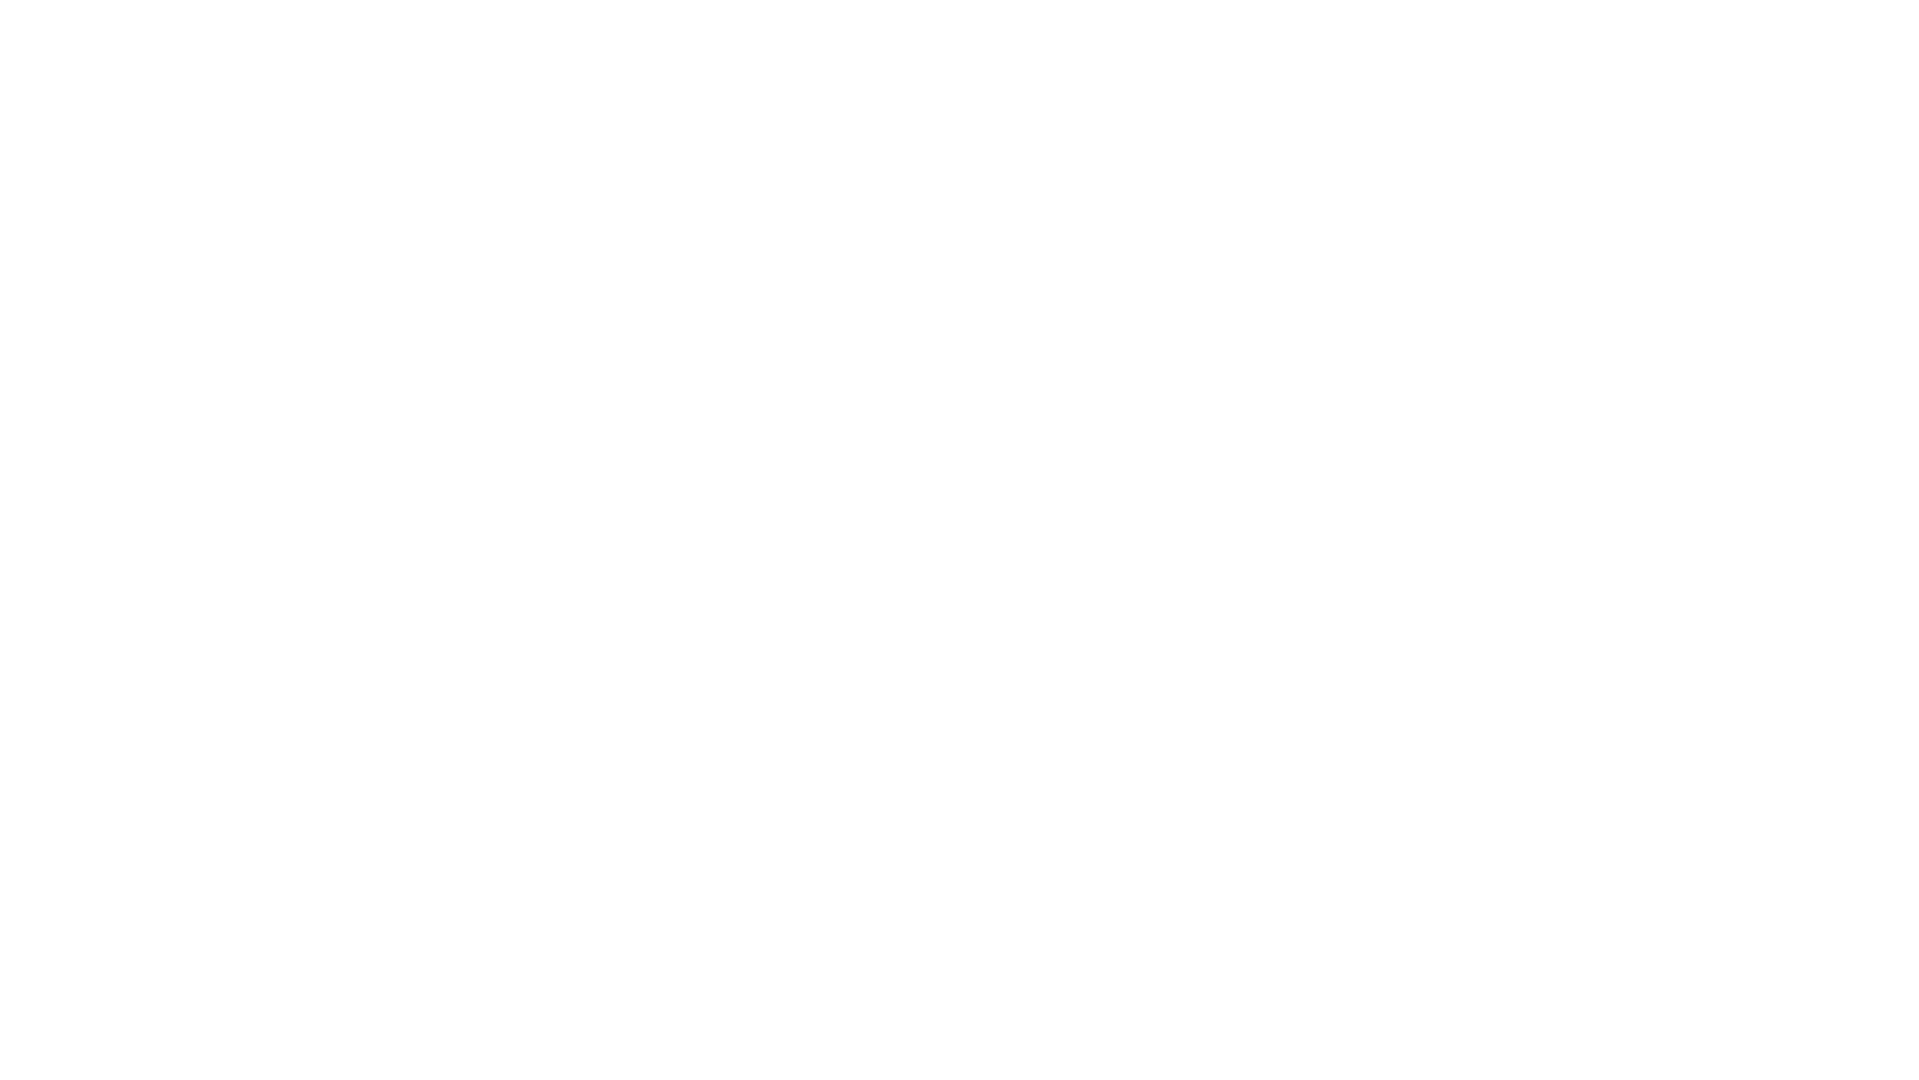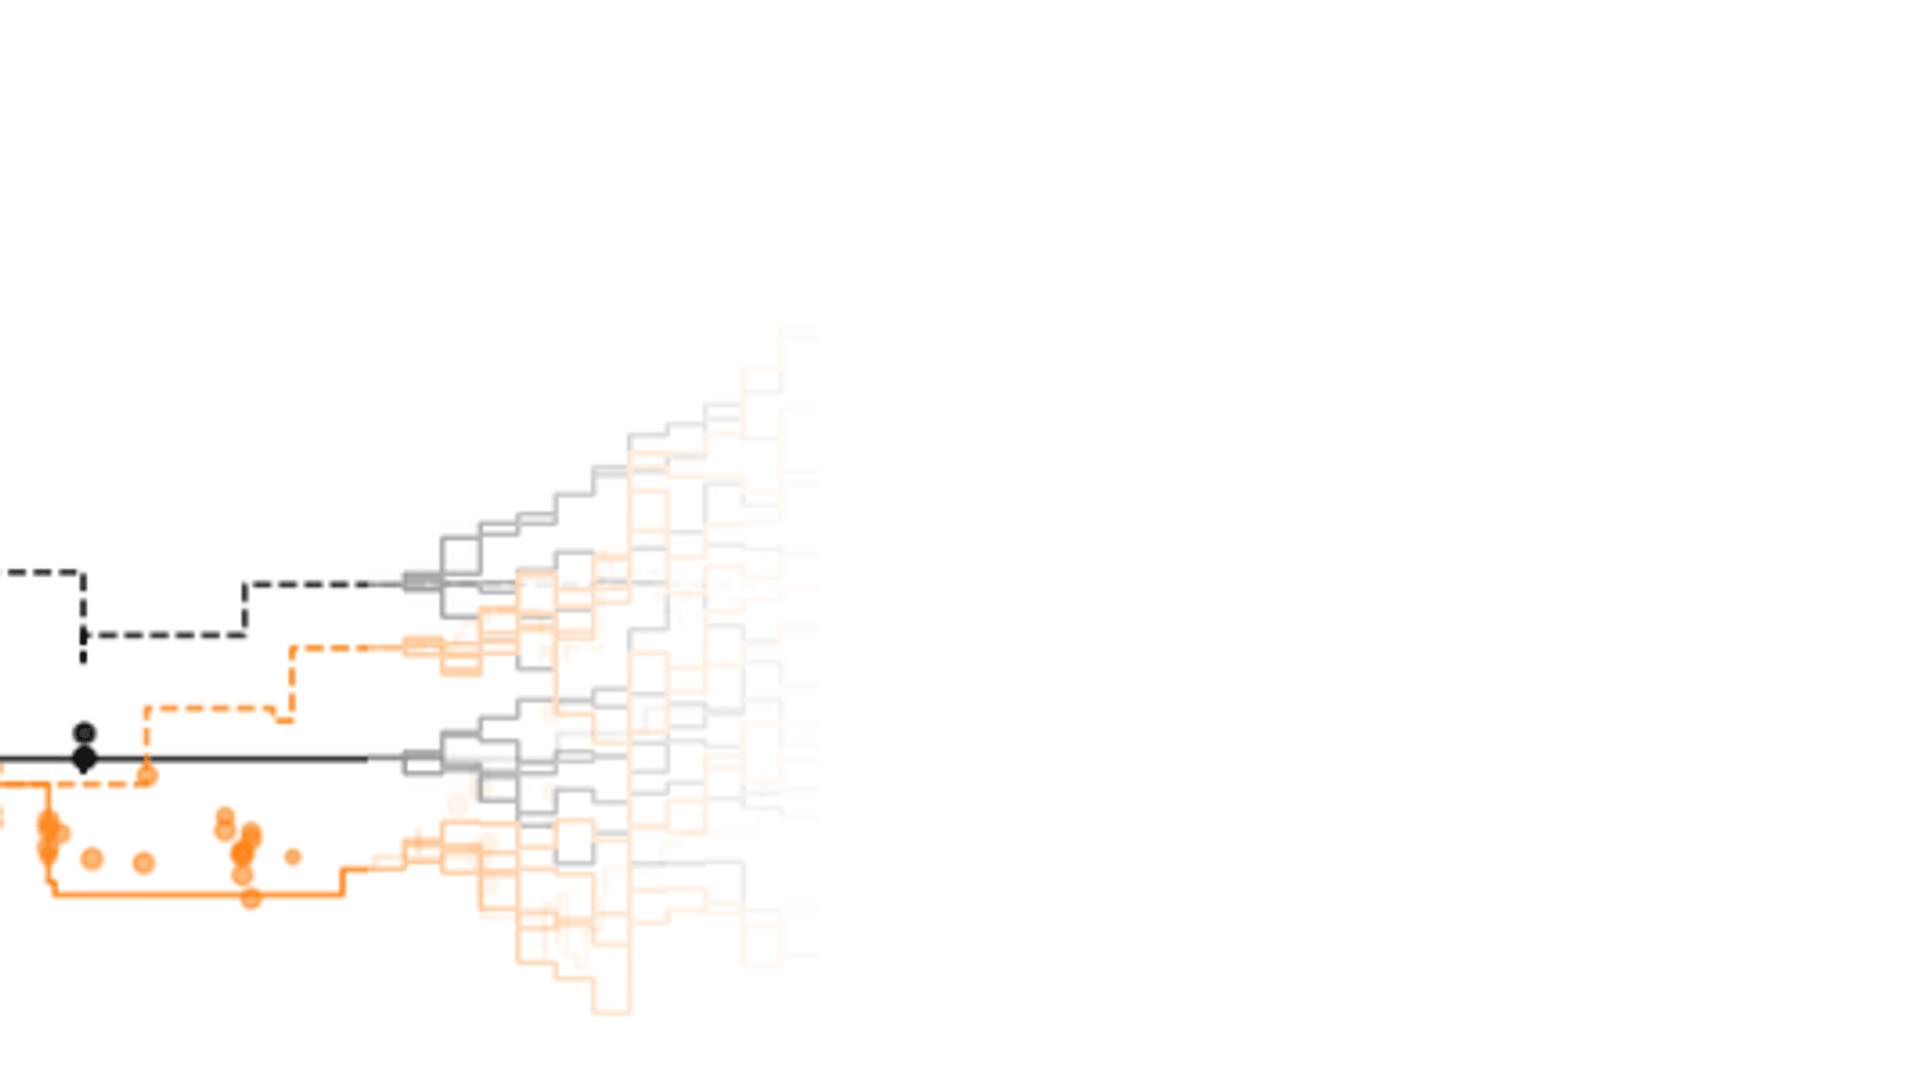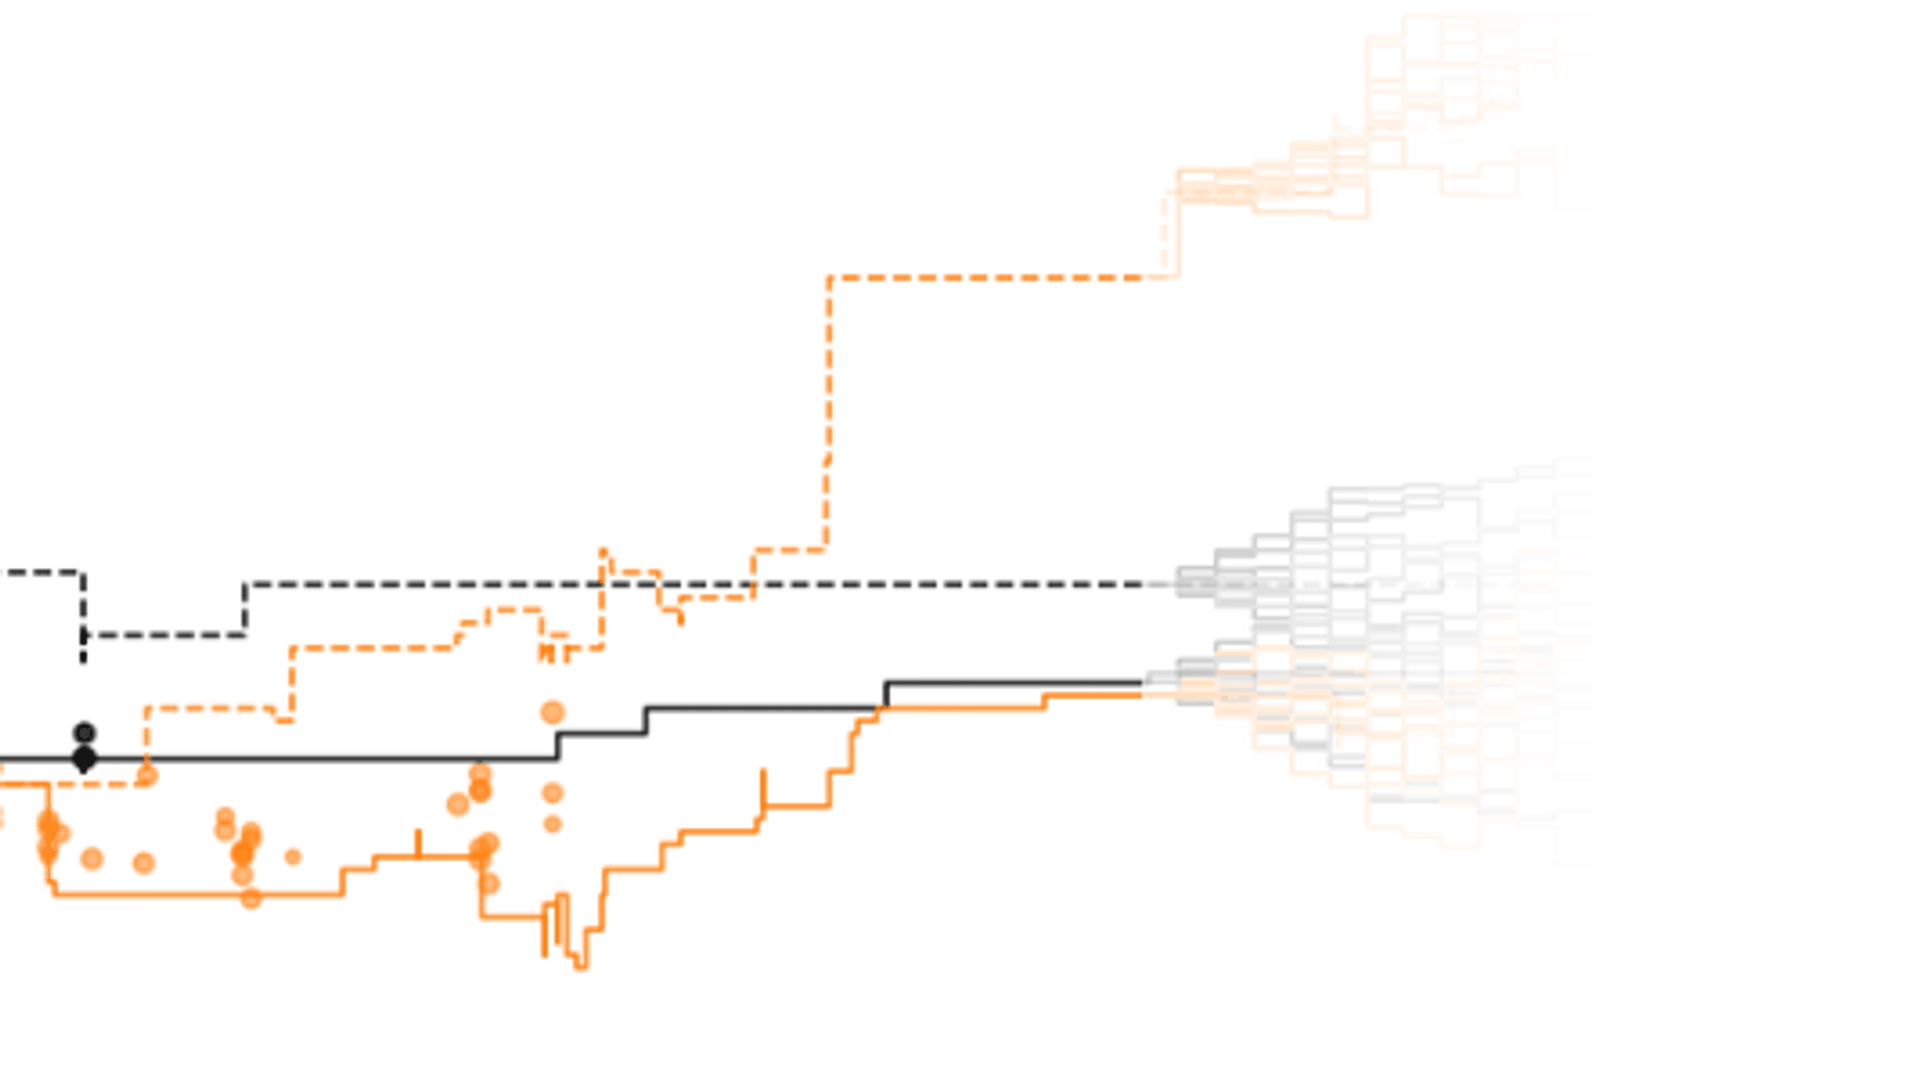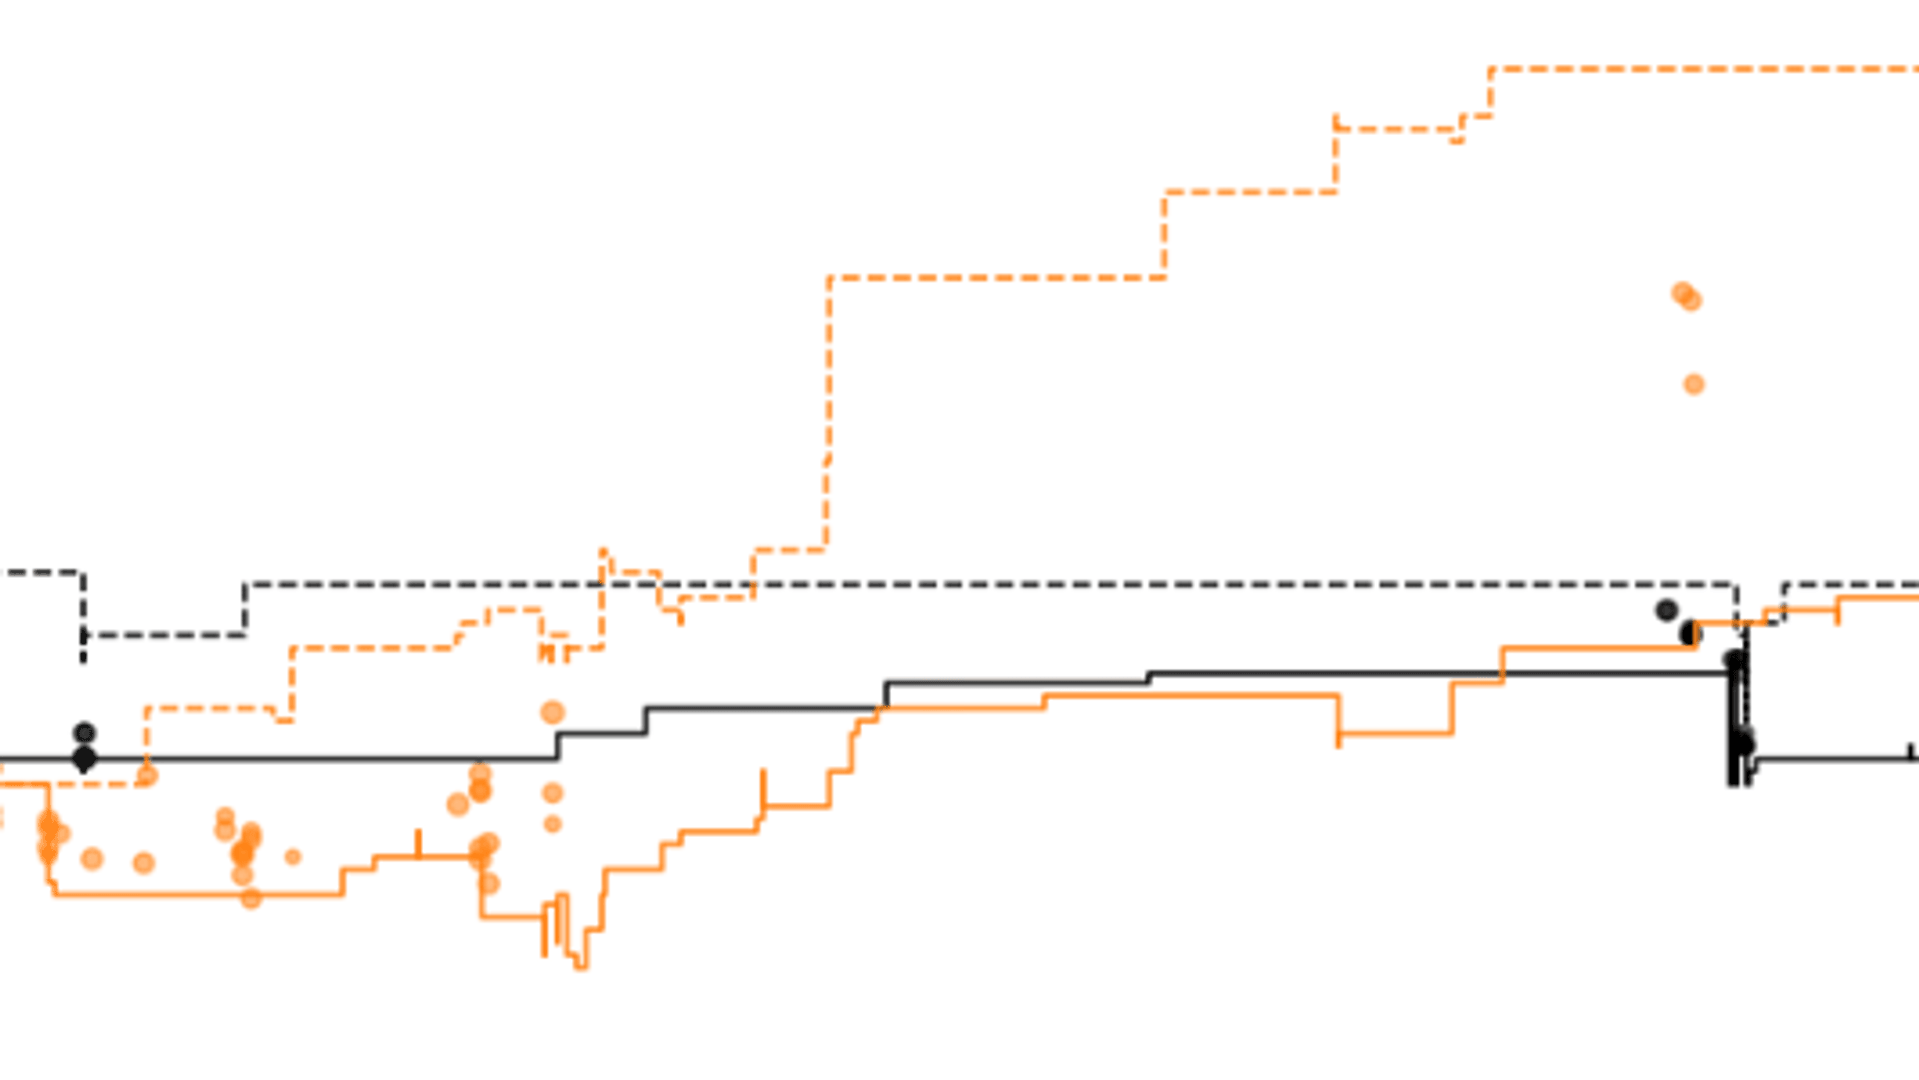
A Jane Street intern developed an autoregressive diffusion model to generate synthetic market data events, including order book updates and trade timings. The research demonstrated that flow matching is more effective than DDPM for this domain and introduced 'atom smoothing' to manage the discrete spikes in financial data distributions. Although the model successfully captures short-term event characteristics, maintaining accuracy over long-term autoregressive sequences remains a significant challenge.
Key Points
- Market data is a hybrid of continuous and discrete features, characterized by 'spiky' distributions and point masses that are difficult for standard diffusion models to capture.
- Flow matching proved superior to DDPM for market data generation, providing more stable denoising trajectories and better handling of high-noise levels.
- To handle discontinuities like simultaneous events or fixed price increments, the researcher developed 'atom smoothing' to redistribute probability mass without losing the underlying discrete structure.
- The model used a transformer-based encoder to produce latent embeddings, which then conditioned a diffusion head for continuous targets and a categorical head for event types.
- Evaluation using a discriminator showed that feature representations optimized for atom smoothing produced significantly more realistic samples than baseline methods.
Sentiment
The community is cautiously positive toward the article's technical contribution and generally treats it as a thoughtful research write-up rather than hype. Agreement is strongest around the difficulty and interest of modeling market microstructure, while skepticism focuses on practical trading edge, continuous approximations, and evaluation. The discussion is mixed but constructive, with more curiosity and qualified appreciation than hostility.
In Agreement
- The article is a strong exposition of applying diffusion and flow-matching ideas to time-series market data with both discrete and continuous characteristics.
- The focus on categorization, conditioning, and atom smoothing usefully addresses the jagged nature of order-book events rather than pretending the data fits a simple format.
- Synthetic order-book generation is a worthwhile research direction because realistic market streams require modeling event timing, discrete actions, and high-cardinality values together.
- Professional market modeling gains practical value from data access and calibrated odds, not just from generic price prediction or headline model sophistication.
Opposed
- Some commenters argue that order books are fundamentally discrete, so describing market data as continuous risks obscuring the actual mechanics of orders and trades.
- Several commenters doubt that any profitable market model can remain accurate for long because market participants eventually absorb and arbitrage away visible signals.
- Commenters question whether generic prediction metrics capture trading usefulness, since timing, latency, and direction can matter more than aggregate statistical accuracy.
- A recurring skeptical view is that model architecture may matter less than privileged data, operational discipline, and whether the signal can be acted on before competitors erase it.